// https://github.com/storj/storj/blob/d6feadb8ddd510412d9134519bce92ccc555094b/satellite/satellitedb/verifyqueue.go#L174-L175

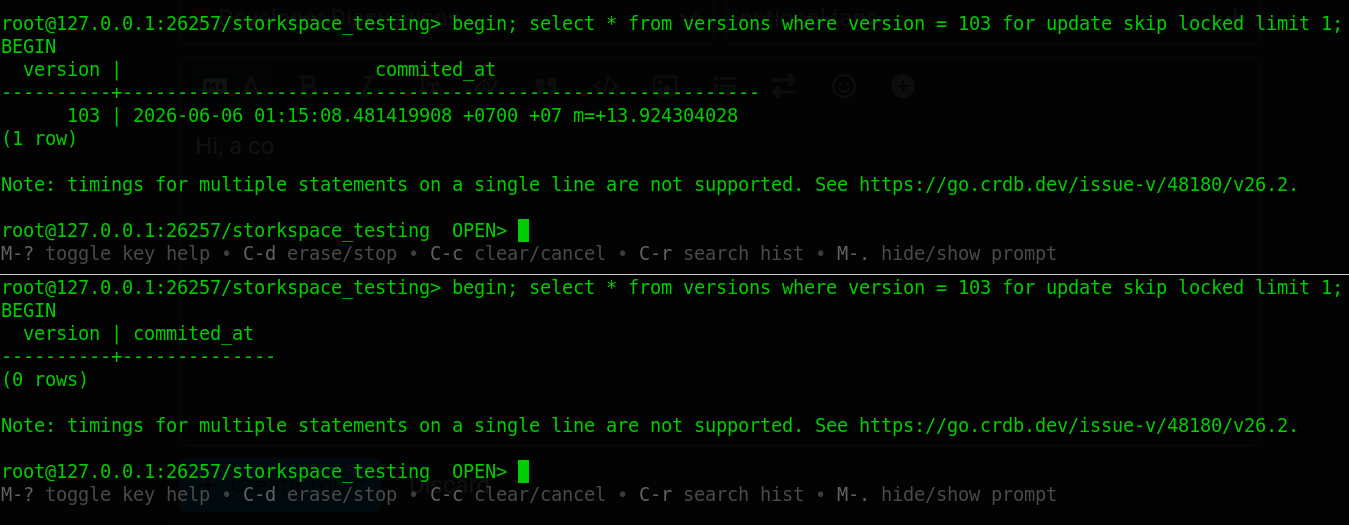
		// Note: because Cockroach does not support SKIP LOCKED, this implementation
		// is likely much less performant under any amount of contention.
		getQuery = `
			WITH next_row AS (
				SELECT inserted_at, stream_id, position
				FROM verification_audits
				ORDER BY inserted_at, stream_id, position
				FOR UPDATE
				LIMIT 1
			)
                        ...
CRDB add support for for update skip locked sometime later:
But last month, when I try to run database migration on crdb latest version - there was some hiccup.
When I try to fix database migration with a PR, @elek told me there was some issue with crdb license and told me I could patch it via Dockerfile entry (as individual using crdb). That work, but does that mean crdb won’t be update in the future?
If Storj don’t support cockroachdb (or spanner) in the future, then the resource to self support as the source code change will become a problem.
For example: Storj could drop crdb/spanner driver (or just neglect the driver). I can totally understand that - no reason to support something you don’t personally use.
But that beg the question, what now? Would spanner/crdb will still be supported (finger cross for crdb)? What the verdict?
It’s too soon to say that, they are also venture capital funding, what guarantee they don’t do the same in the future? Are we drifting to a new database?
Of all thing, only postgres is here to stay, and it close friend crdb support will be easier.
And, just personally, I just think crdb is the superior product .
We are thinking about removing support for Spanner and CockroachDB. Reasoning for Spanner is pretty obvious, it’s closed solution, we are moving out of Spanner now and maintaining additional database is a big effort. With CRDB situation looks that they change their licensing down the road and effectively it become unusable for us as an open source solution and as I wrote earlier maintaining additional database is a big effort.
But last month, when I try to run database migration on crdb latest version - there was some hiccup.
Because of licensing our test suites are running only against quite old versions so we cannot guarantee anything with latest versions.
Not very hard, we used AI to prototype few backends to select best option for us. We have very extensive test coverage so AI have good base to create working implementation. It might not be optimal but it will work.
No, it’s exactly how it was performed. We tested several candidates before select the best of them.
Of course in many cases CRDB would be better, but as explained above it doesn’t match our Open Source approach, like a Spanner as well.
I read it differently: using crdb in production is different than just maintaining it, I think storj afraid of the resource to maintain it, I can take that role, if they don’t use it in production, no way cockroach labs will be able to go after them
crdb is better product for small satellite (the 10M a year revenue… not even Storj Labs have it). I could maintain it if storj can’t since it pretty much syntax identical to postgres.
it simply better - since the leader (postgres) is better, this blog said better than me why-postgres.
Personally, I report a few logical bugs in mysql, concurrency bug - nasty in production, create a reproduce, they verified but it stay for years (can’t check anymore since oracle change login)..
So at the moment we have no time to do analysis if we can use latest crdb (even without using it in prod) or not but maybe we could accept change 2 and 3. But as it was mentioned I think might be dead end if you plan to maintain satelite long term.

 .
 , saw recent commits, is crdb here to stay?

 .