Hello,
I have a very old node that had power issue that required a full fsck (1 day).
After it not wanted to start and I had to remove s0 and s1 directory under hashstore
It started working for almost a day and then it started complaining about piecemigrate / file corrupted.
I removed the files and i have no more errors but node is in loop
See below logs
Thanks
2026-08-15T18:06:44Z INFO piecemigrate:chore all enqueued for migration; will sleep before next pooling {“process”: “storagenode”, “active”: {“121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”: true, “12EayRS2V1kEsWESU9QMRseFhdxYxKicsiFmxrsLZHeLUtdps3S”: false, “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”: true, “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”: true}, “interval”: “10m0s”}
2026-08-15T18:16:34Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”}
2026-08-15T18:16:45Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”}
2026-08-15T18:16:47Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”}
2026-08-15T18:16:47Z INFO piecemigrate:chore all enqueued for migration; will sleep before next pooling {“process”: “storagenode”, “active”: {“12EayRS2V1kEsWESU9QMRseFhdxYxKicsiFmxrsLZHeLUtdps3S”: false, “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”: true, “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”: true, “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”: true}, “interval”: “10m0s”}
2026-08-15T18:26:34Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”}
2026-08-15T18:26:42Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”}
2026-08-15T18:26:46Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”}
2026-08-15T18:26:46Z INFO piecemigrate:chore all enqueued for migration; will sleep before next pooling {“process”: “storagenode”, “active”: {“12EayRS2V1kEsWESU9QMRseFhdxYxKicsiFmxrsLZHeLUtdps3S”: false, “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”: true, “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”: true, “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”: true}, “interval”: “10m0s”}
2026-08-15T18:36:34Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”}
2026-08-15T18:36:49Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”}
2026-08-15T18:36:50Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”}
2026-08-15T18:36:50Z INFO piecemigrate:chore all enqueued for migration; will sleep before next pooling {“process”: “storagenode”, “active”: {“12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”: true, “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”: true, “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”: true, “12EayRS2V1kEsWESU9QMRseFhdxYxKicsiFmxrsLZHeLUtdps3S”: false}, “interval”: “10m0s”}
2026-08-15T18:46:34Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”}
2026-08-15T18:46:34Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”}
2026-08-15T18:46:34Z INFO bandwidth Persisting bandwidth usage cache to db {“process”: “storagenode”}
2026-08-15T18:46:44Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”}
2026-08-15T18:46:46Z INFO piecemigrate:chore all enqueued for migration; will sleep before next pooling {“process”: “storagenode”, “active”: {“1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”: true, “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”: true, “12EayRS2V1kEsWESU9QMRseFhdxYxKicsiFmxrsLZHeLUtdps3S”: false, “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”: true}, “interval”: “10m0s”}
This isn’t a loop. The node runs the migration every ten minutes or so. The reason is that there may still be pieces in the piecestore trash that can be recovered, and in that case they would need to be migrated to hashstore as well.
You can simply ignore this. If it bothers you and there are no pieces left in the piecestore trash, you can remove the migration config.
@zip is correct in general - the node run migration every 10 minutes by default.
But the trash will not be migrated to hashstore, since it will be deleted after a week anyway.
However, it could be recovered by a command from the satellite. This is a rare case, but it’s possible. For example, we could sent a corrupted or not full BF, so nodes will move to the trash pieces, which should remain. In that case we can call a restore and save customers’ data.
Hi all,
I can understand the background migration, but the node is no more opened to commercial traffic (no upload or download).
It’s not reported as online.
Now are 2 days.
Is there a way to stop the migration and restart the node in order to receive data ?
Thank
2026-08-16T03:56:36Z INFO piecemigrate:chore all enqueued for migration; will sleep before next pooling {“process”: “storagenode”, “active”: {“121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”: true, “12EayRS2V1kEsWESU9QMRseFhdxYxKicsiFmxrsLZHeLUtdps3S”: false, “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”: true, “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”: true}, “interval”: “10m0s”}
2026-08-16T04:06:37Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”}
2026-08-16T04:06:37Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”}
2026-08-16T04:06:37Z INFO piecemigrate:chore enqueued for migration {“process”: “storagenode”, “sat”: “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”}
2026-08-16T04:06:37Z INFO piecemigrate:chore all enqueued for migration; will sleep before next pooling {“process”: “storagenode”, “active”: {“12EayRS2V1kEsWESU9QMRseFhdxYxKicsiFmxrsLZHeLUtdps3S”: false, “12L9ZFwhzVpuEKMUNUqkaTLGzwY9G24tbiigLiXpmZWKwmcNDDs”: true, “1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE”: true, “121RTSDpyNZVcEU84Ticf2L1ntiuUimbWgfATz21tuvgk3vzoA6”: true}, “interval”: “10m0s”}
The migration doesn’t render the node as offline. You need to check usual things: compare your WAN IP on your router with the IP on yougetsignal, if they don’t match, then your ISP switched your connection behind CGNAT.
If they match, then you need to update your external address to match it or even better - use the DDNS hostname and the DDNS updater on your router: Running a V3 Storage Node with VPN - Storj Docs
Sorry ,
I mean that the node is no more receiving traffic.
No upload and No download
It’s still blocked
I can’t see any progress
Could you kindly provide me a way to understand if it’s progressing and how many time is still needed ?
2nd - to fix another problem I deleted s0 and s1 directories in hashstore for al satellite. Is this something wrong that could lead to issues ? Maybe the one I had
Is it online? The ingress or egress cannot be blocked by a migration by design.
Why you did this? And which ones - with hash tables or with logs? If with logs, your node is likely disqualified for the lost data.
If with hashtables, then you need to wait until the node will recover them back. How long it will take depends on the amount of data, a power of your system and the disk subsystem speed. Many reported days. During recovery the node will be offline.
Hello,
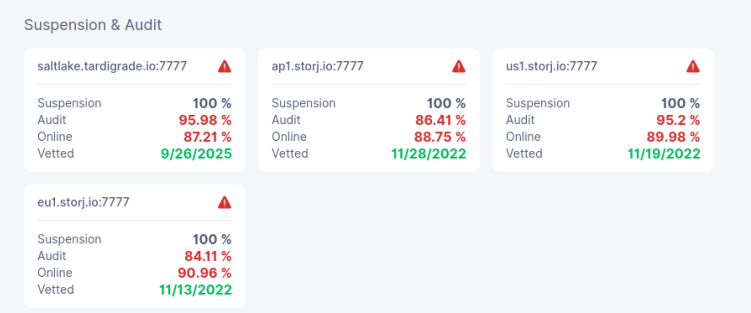
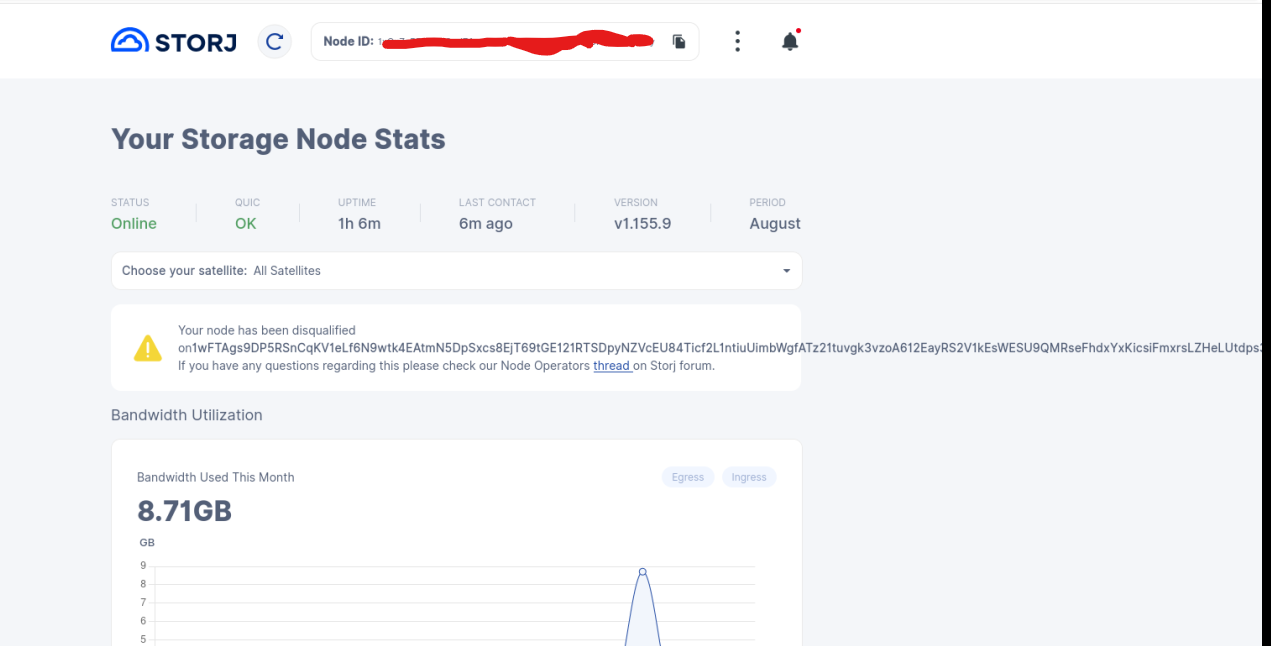
as per attached image it seems to be disqualified at least on one satellite. Not sure, can you confirm ?
The node is online but there is not activity, just enqueue notification. Neither a success or progress . Not sure if it’s doing something in the background.
I renamed s0 and s1 in the path /mount_point/storage/hashstore/1wFTAgs9DP5RSnCqKV1eLf6N9wtk4EAtmN5DpSxcs8EjT69tGE/ to fix another issue. AI information, maybe wrong.
Any suggestion ?
Hi Alexey,
thanks to confirm , I will delete storagenode4 and recreate it.
This is the full picture of all my nodes and I have others disqualified in one satellite but full working (upload and download are comings)
pi4 - storagenode - healty
hpool - storagenode3 - DISQ 12Eay - running with errors
hpool2 - storagenode7 - heatly - running
hpool3 - storagenode8 - healty - running
hpool4 - storagenode4 - DISQ 1wFTA - blocked tb deleted
hpool6 - storagenode6 - DISQ 1wFTA - running
hpool7 - storagenode2 - DISQ 1wFTA - running
What should I do here (for the one still working on other satellite ?)
gracefull exit and spin up new nodes in parallel ?
leave as is, spin up new nodes and then gracefull exit ?
leave as is and the satellite will be recovered ?
PS I have a major power outage issue that caused my servers to crash 5 times in a few times. Some restart also during fsck. a mess.
If the node is not DQ on all satellites yet, you can continue to run it. If it’s DQ on all satellites - delete the identity and its data and start fresh (with generation a new identity for each node, don’t clone, all clones will be DQ almost instantly).
However, I would like to suggest to investigate, why they were DQed. If due to your actions - then please do not do them again.