Did you stop node and delete databases? It usualy helps.
That’s an interesting suggestion. No I have not yet tried that.
As explained above, it reserves this space for compaction. I don’t know your configuration options for hashstore, but might guess that you configured it to be aggressive to have less reclaimable space. So the node expects to have a free space to make it.
Please show, how much reclaimable space it contains?
I wonder what would happen after the compaction will be done?
If that’s the case then it explains what I am saying in other words: The node occupies space (in my case 1.3TB?) that cannot be used for uploads. Thereofere it is unpaid occupied space like trash.
Still I don’t get it why the node believes it requires 1.3TB for compaction at allocated space of 5.5TB and zero at allocation of 5.6TB?
I mean the “fix” is easy: Add at least 100GB to the allocation and the node gets ingress again. But for me it does not seem logical what the node is doing.
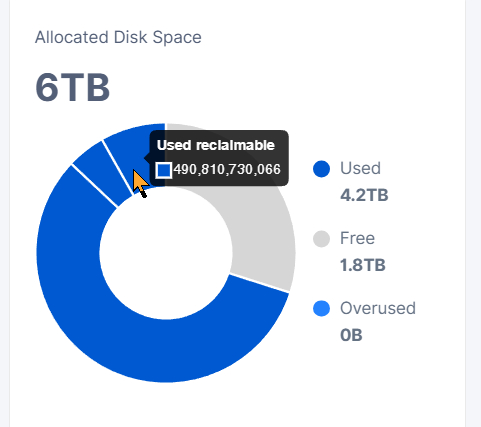
I am running the node with allocated 6TB currently to be safe that it does not get cut off from ingress again.
I think it still wants to have 1.3TB, but while it has more, it doesn’t block it.
However, I want to get a confirmation from the team that’s expected behavior.
Could it be a leftover from an incomplete piecestore count in the database, lurking since your transition to hashstore?
activate your flags, if they were off.
storage2.piece-scan-on-startup
pieces.enable-lazy-filewalker
1.55 cents,
Julio
The lazy mode should stay off. It created all sorts of problems. And it is not needed anymore with hashstore. I sugest removing the code along with the piecestore part, when time comes.
That’s the plan. When all nodes will migrate to hashstore we plan to remove the piecestore related code.