Did some folks already turned off their rigs (high repair)?

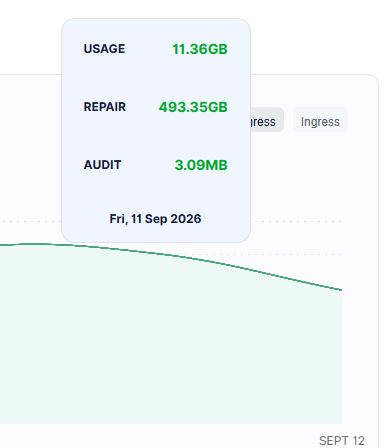
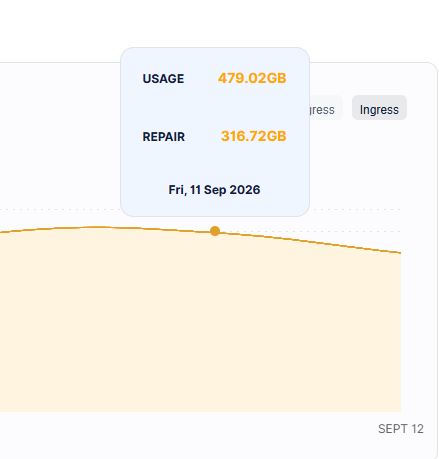
Recent days, I noticed a very high repair, ingress and egress wise. In my case 505GB egress/repair, 15GB egress/usage and 310 ingress/repair, 471GB ingress/usage. There were times with high repairs in the past, but this ratio is “new” also for ingress (in my case).

Did you noticed similar behavior?

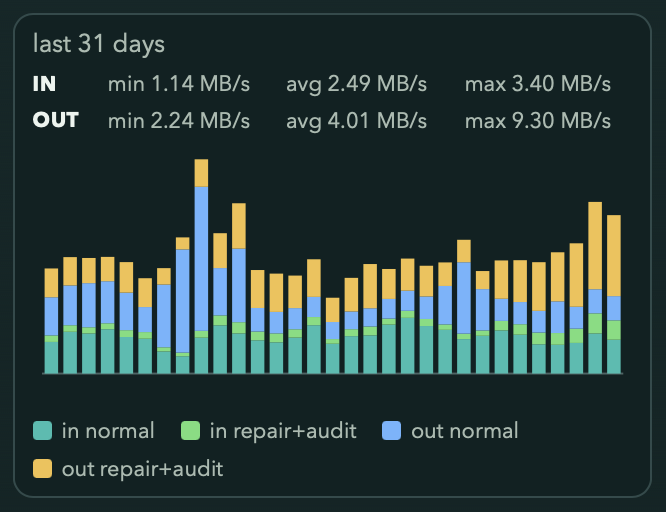
I don’t see any significant difference in the past month. Yellow is repair.

What is out repair and in repair?
I guess “in repair” are the pieces “moved” to your node from other ones. But what is “out”?

The repair egress from their nodes.
We adjusted RS numbers several months ago, so now it’s noticeable.
The repair workers downloads missed pieces.

Date       |  GET_AUDIT | GET_REPAIR | PUT_REPAIR |        GET |        PUT
===========+============+============+============+============+=============
2026-09-03 |      42952 |     157030 |     454423 |    1962259 |     837478
2026-09-04 |      52356 |     137041 |     367339 |    2511068 |     718060
2026-09-05 |      56140 |     333556 |     770160 |    2351905 |     883165
2026-09-06 |      66803 |     551956 |    1266504 |    2836181 |    1231079
2026-09-07 |      75056 |     490340 |    1084581 |    3191220 |     960957
2026-09-08 |      77789 |     463571 |    1129989 |    3805527 |     952881
2026-09-09 |      80006 |     763994 |    1458308 |    3959563 |     980490
2026-09-10 |      85794 |    1007237 |    1851661 |    4414135 |    1235652
2026-09-11 |      90576 |    1319653 |    2195952 |    4587262 |    1146359

about 300 nodes was DQ some days ago

There is 23800 nodes offering free space in global network atm. So most of “right sizing” still ahead.

Traffic yesterday:


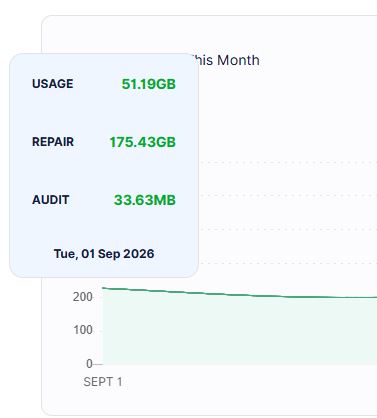
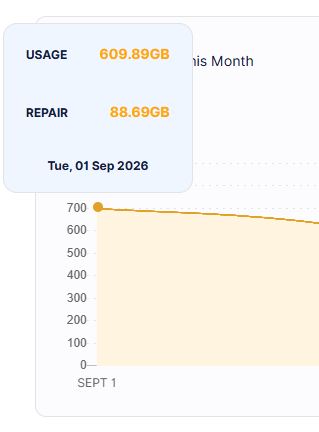
VS. Traffic in 1st Sept.


In my case the proporions changes are huge.

This is the count of repair get and put operations, not storage volume so it may be skewed, but the count seems to have increased a bit on my end. Going back even a few months I don’t see a jump quite this high.

I’m not sure if this is actual node departure or the RS changes mentioned, my nodes all seem to be both taking in and sending more repair traffic.

12 were mine. Unfortunately I turned off about 200 TB of data. :zipper_mouth_face:


Same here, 16 nodes 186TB currently in ‘graceful exit’ with 19 days left.

The Storj developers have created a fantastic product but with the total disasters on the management side, both the old and the new with Inveniam in the background, I have lost all confidence in Storj.

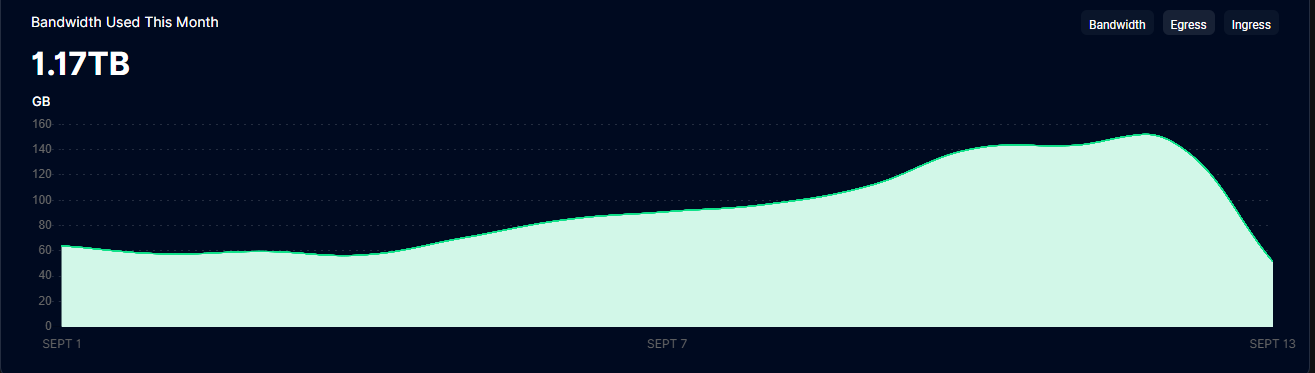
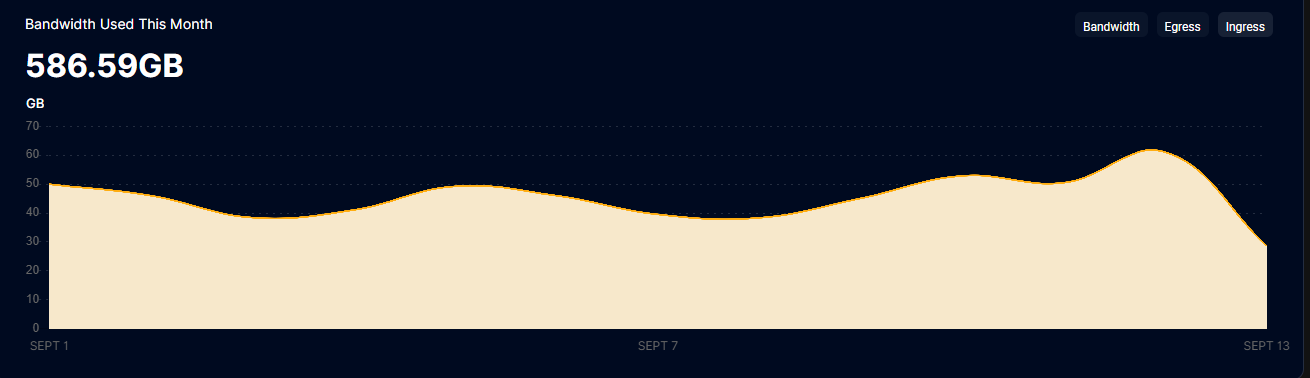
I also see a lot of repair egress these days. Repair ingress is a bit higher then usual, but not by much. I expected a lot more data with big SNO’s leaving the network.

Egress:

Ingress:

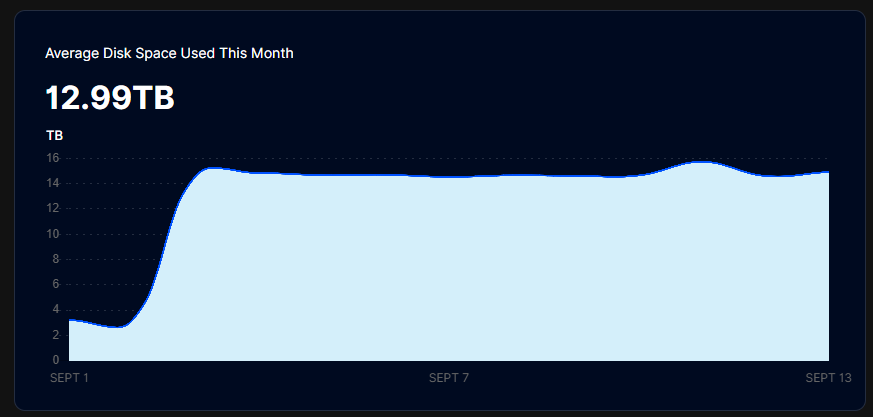
Average disk space is stable (nodes are fully migrated to hashstore)

It could be a usual wave of a repair traffic. Nodes can lost data due to many reasons. It usually happens over time. So today you are likely seeing a repair traffic for the data uploaded a few years ago.