[Tutorial] Run your own satellite (part 10) - Introducing mud and ranged-loop

Have you ever wonder, why we have satellite-modular or even storagenode-modular? Why not just have a single satellite binary?

I mean, a single binary work too, that is if you want to have 50+ binaries to work with and who know how many more will come.

Introducing mud[1].


What is mud? What does it do?

In practical term, you can change satellite services behavior with --components flag, specifically: you can include/exclude components at runtime, or even use a different implementation to a problem.

This is particular important with ranged-loop. Normally, ranged-loop service would do nothing, unless you force it to do something via --components. (Unlike most of our previous tutorials).

Okay, got the general idea, how can I list which component I could use for a command?

Hmm… you can’t, technically there is, but realistically, this is a tool for developer who already know what they gonna do, not an exploration tool for operator, you have to read code to know which component you can use.

That said, because I already go through it once, I could give you some direction (and you have to read code or ask AI to explain it to you).

Keyword that actually matter: mud.RegisterInterfaceImplementation, mud.Optional (for ranged-loop - most thing are optional and won’t get run by default), mud.Implementation.

Can I not read it?

You don’t have to for now, I’m gonna do it for the next tutorial anyway, but this is one of the core concept of StorJ source code, the source code will change and this tutorial will not last forever..


See you on part 11 where we will dive deep into ranged-loop.


Update Aug 31:

To see all components, use this command:

./satellite-modular exec --debug-components='all' # counting 439 lines

Due to too large number of components, the original plan to documenting all components will be on halt, I’ll redirect effort to make a public community satellite and occasionally updating this, this is a wiki so feel free to continue document and attach link below.

Documented components:

Auxiliaries


  1. github - introduction to mud ↩︎

ranged-loop is supposed to run all child services in a single sweep

Reason? If you run ranged-loop with each child service separatedly, each service will querying database independently, it cannot reuse data queried from database.

Best is to run all ranged-loop service in a single command, that is probably why ranged-loop exist in the first place.

Content below are for educational purposes, don’t run it blindly on production.

$checker.Observer

$checker.Observer is the repair checker: the satellite’s damage detector. Its one job is to answer, for every remote segment in the network, a single question — does this segment still have enough healthy pieces, in the right places, to be safe? — and to write down the ones that don’t.

It doesn’t fix anything. It produces a to-do list. The actual reconstruction is done by a completely separate subsystem (satellite/repair/repairer) that reads that list. This separation is deliberate: detection is a cheap, read-only full-table scan; repair is expensive, network-bound, and needs to be rate-limited independently.

– Claude

Minimum useful command to run:

./satellite-modular ranged-loop --components='$checker.Observer' \
--database-options.url "cockroach://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=/ca.crt" \
--identity-dir=id/satellite \
--jobq.server-node-url '12kK7Y15fU1b5YADYRiBj2Dd4WsF1LARVWHpW6nXRcusV3wiRZD@127.0.0.1:15781' \
--jobq.tls.extensions.revocation=false \
--jobq.tls.use-peer-ca-whitelist=false \
--metainfo.database-url "cockroach://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt"

If thing go well it should look like this (jobq service must already up):

2026-07-28T02:05:01+07:00 INFO debug:wrapper.debug debug server is started listening {"addr": "127.0.0.1:43759"}
2026-07-28T02:05:01+07:00 INFO tracing:tracing Anonymized tracing enabled
2026-07-28T02:05:01+07:00 INFO rangedloop:service ranged loop initialized
2026-07-28T02:05:01+07:00 INFO rangedloop:service ranged loop started {"parallelism": 2, "batch_size": 2500, "observers": ["*rangedloop.LiveCountObserver", "*piecetracker.Observer", "*checker.Observer"], "asofsystem_interval": "-5m0s", "spannerstale_interval": "0s"}
2026-07-28T02:05:01+07:00 INFO piecetracker:observer piecetracker observer finished
2026-07-28T02:05:01+07:00 INFO rangedloop:service ranged loop finished

$bloomfilter.Observer

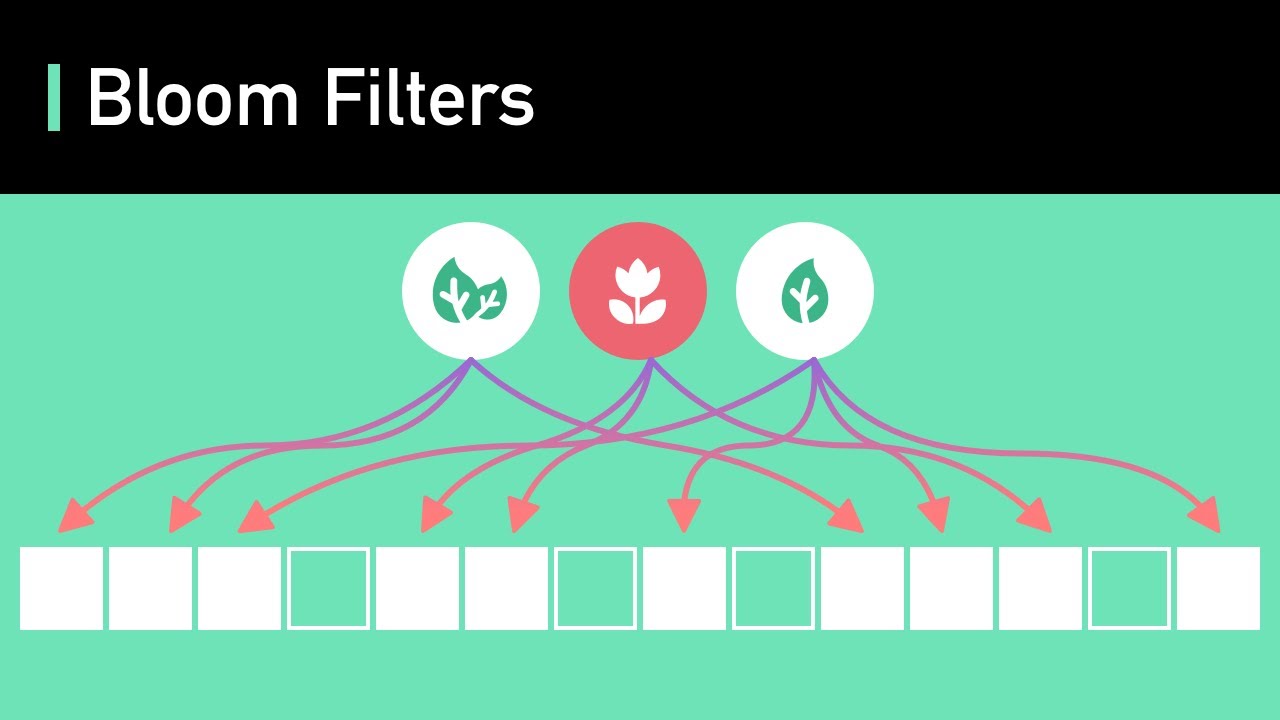
What is a bloomfilter? This video explain the concept nicely:

And what is with V2? Bloomfilter going from $bloomfilter.Observer to $bloomfilter.SyncObserver to $bloomfilter.SyncObserverV2, implementation details :smile:, you only need to care for the latest version (the best implementation so far).

With latest commit, old bloomfilter implementation removed and $bloomfilter.SyncObserverV2 renamed to $bloomfilter.Observer.

Preparation

Two things we need to do:

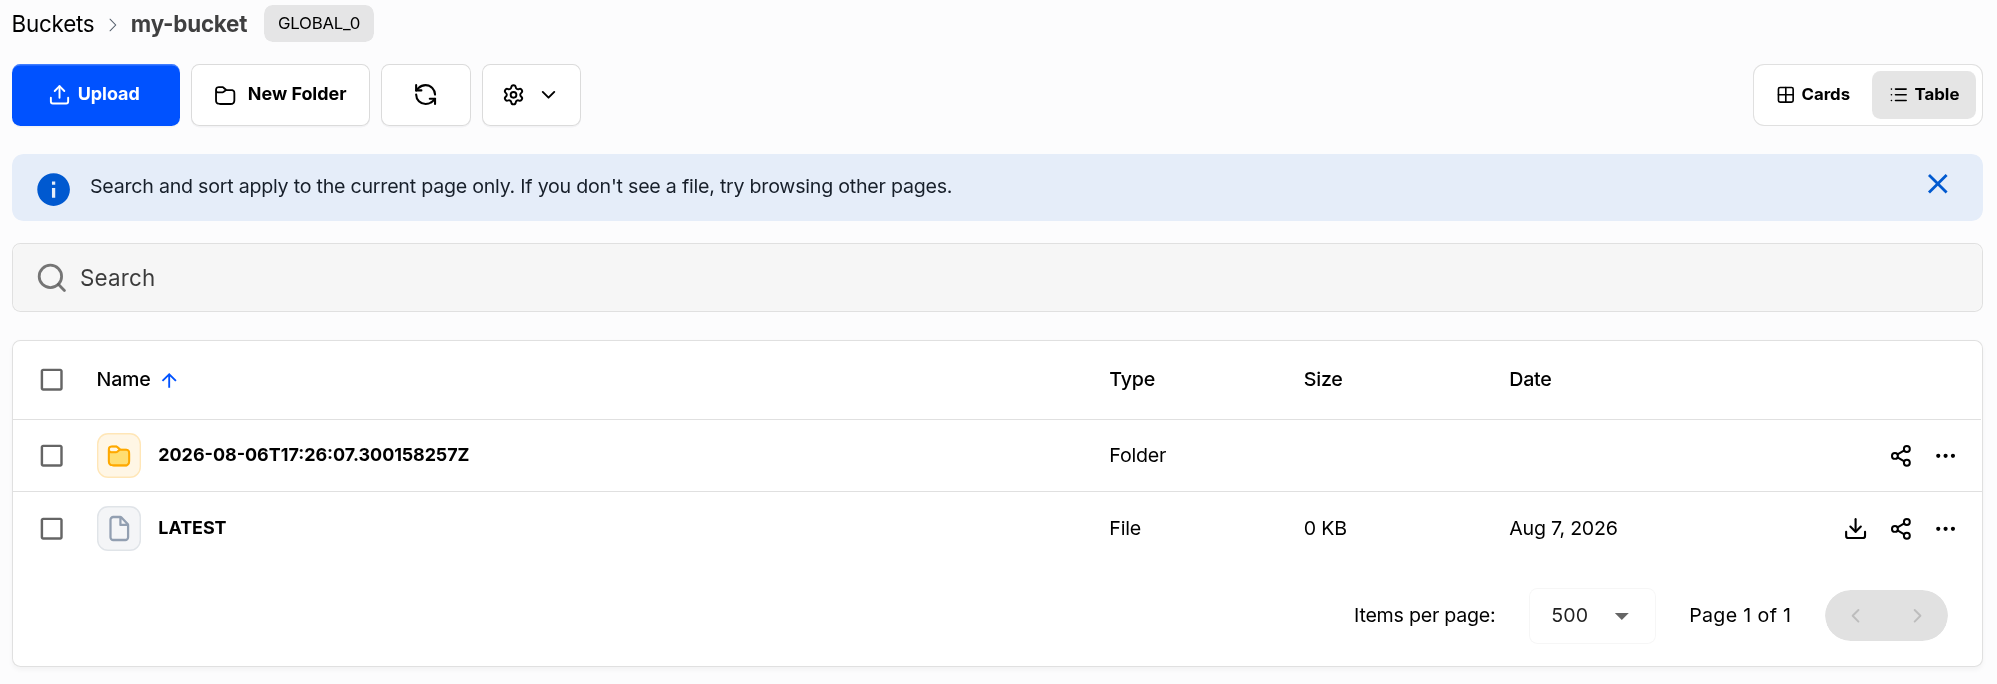
  1. First, we need a bucket for these bloomfilter, you create an account on this satellite, then create a bucket.

  2. Then create an access key for your bucket, you’d need 4 permissions: read, write, list, delete. Other high level permissions - you don’t need it.

Minimum command to run bloomfilter

Bloomfilter is a bit different, you wouldn’t want this service to be run non-stop, maybe trigger it once a week is good enough.

./satellite-modular ranged-loop-once \
--ranged-loop.stale-interval 10m \
--components='$bloomfilter.Observer' \
--database-options.url "cockroach://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=/ca.crt" \
--identity-dir=id/satellite \
--metainfo.database-url "cockroach://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt" \
--garbage-collection-bf.bucket "my-bucket" \
--garbage-collection-bf.access-grant "1AbCdEf..." # access-grant key to your bucket

If thing go right, you would see this:

2026-08-06T17:25:08Z    INFO    debug:wrapper.debug     debug server is started listening       {"addr": "127.0.0.1:34517"}
2026-08-06T17:25:08Z    INFO    tracing:tracing Anonymized tracing enabled
2026-08-06T17:25:08Z    INFO    rangedloop:runonce      ranged loop started     {"parallelism": 2, "batch_size": 2500, "observers": ["*rangedloop.LiveCountObserver", "*piecetracker.Observer", "*bloomfilter.SyncObserverV2"], "asofsystem_interval": "-5m0s", "stale_interval": "10m0s"}
2026-08-06T17:25:18Z    INFO    rangedloop:metabaserangesplitter        Setting fixed read timestamp    {"timestamp": "2026-08-06T17:15:18Z"}
2026-08-06T17:26:07Z    INFO    piecetracker:observer   piecetracker observer finished
2026-08-06T17:26:08Z    INFO    bloomfilter:syncobserverv2      collecting bloom filters finished       {"inline_segments": 10513498, "remote_segments": 1994943}
2026-08-06T17:26:08Z    INFO    rangedloop:runonce      ranged loop finished
2026-08-06T17:26:08Z    INFO    rangedloop:runonce      Ranged-loop observer finished   {"duration": "3.957382ms", "observer": "*rangedloop.LiveCountObserver"}
2026-08-06T17:26:08Z    INFO    rangedloop:runonce      Ranged-loop observer finished   {"duration": "1.223707632s", "observer": "*piecetracker.Observer"}
2026-08-06T17:26:08Z    INFO    rangedloop:runonce      Ranged-loop observer finished   {"duration": "1m14.960450498s", "observer": "*bloomfilter.SyncObserverV2"}

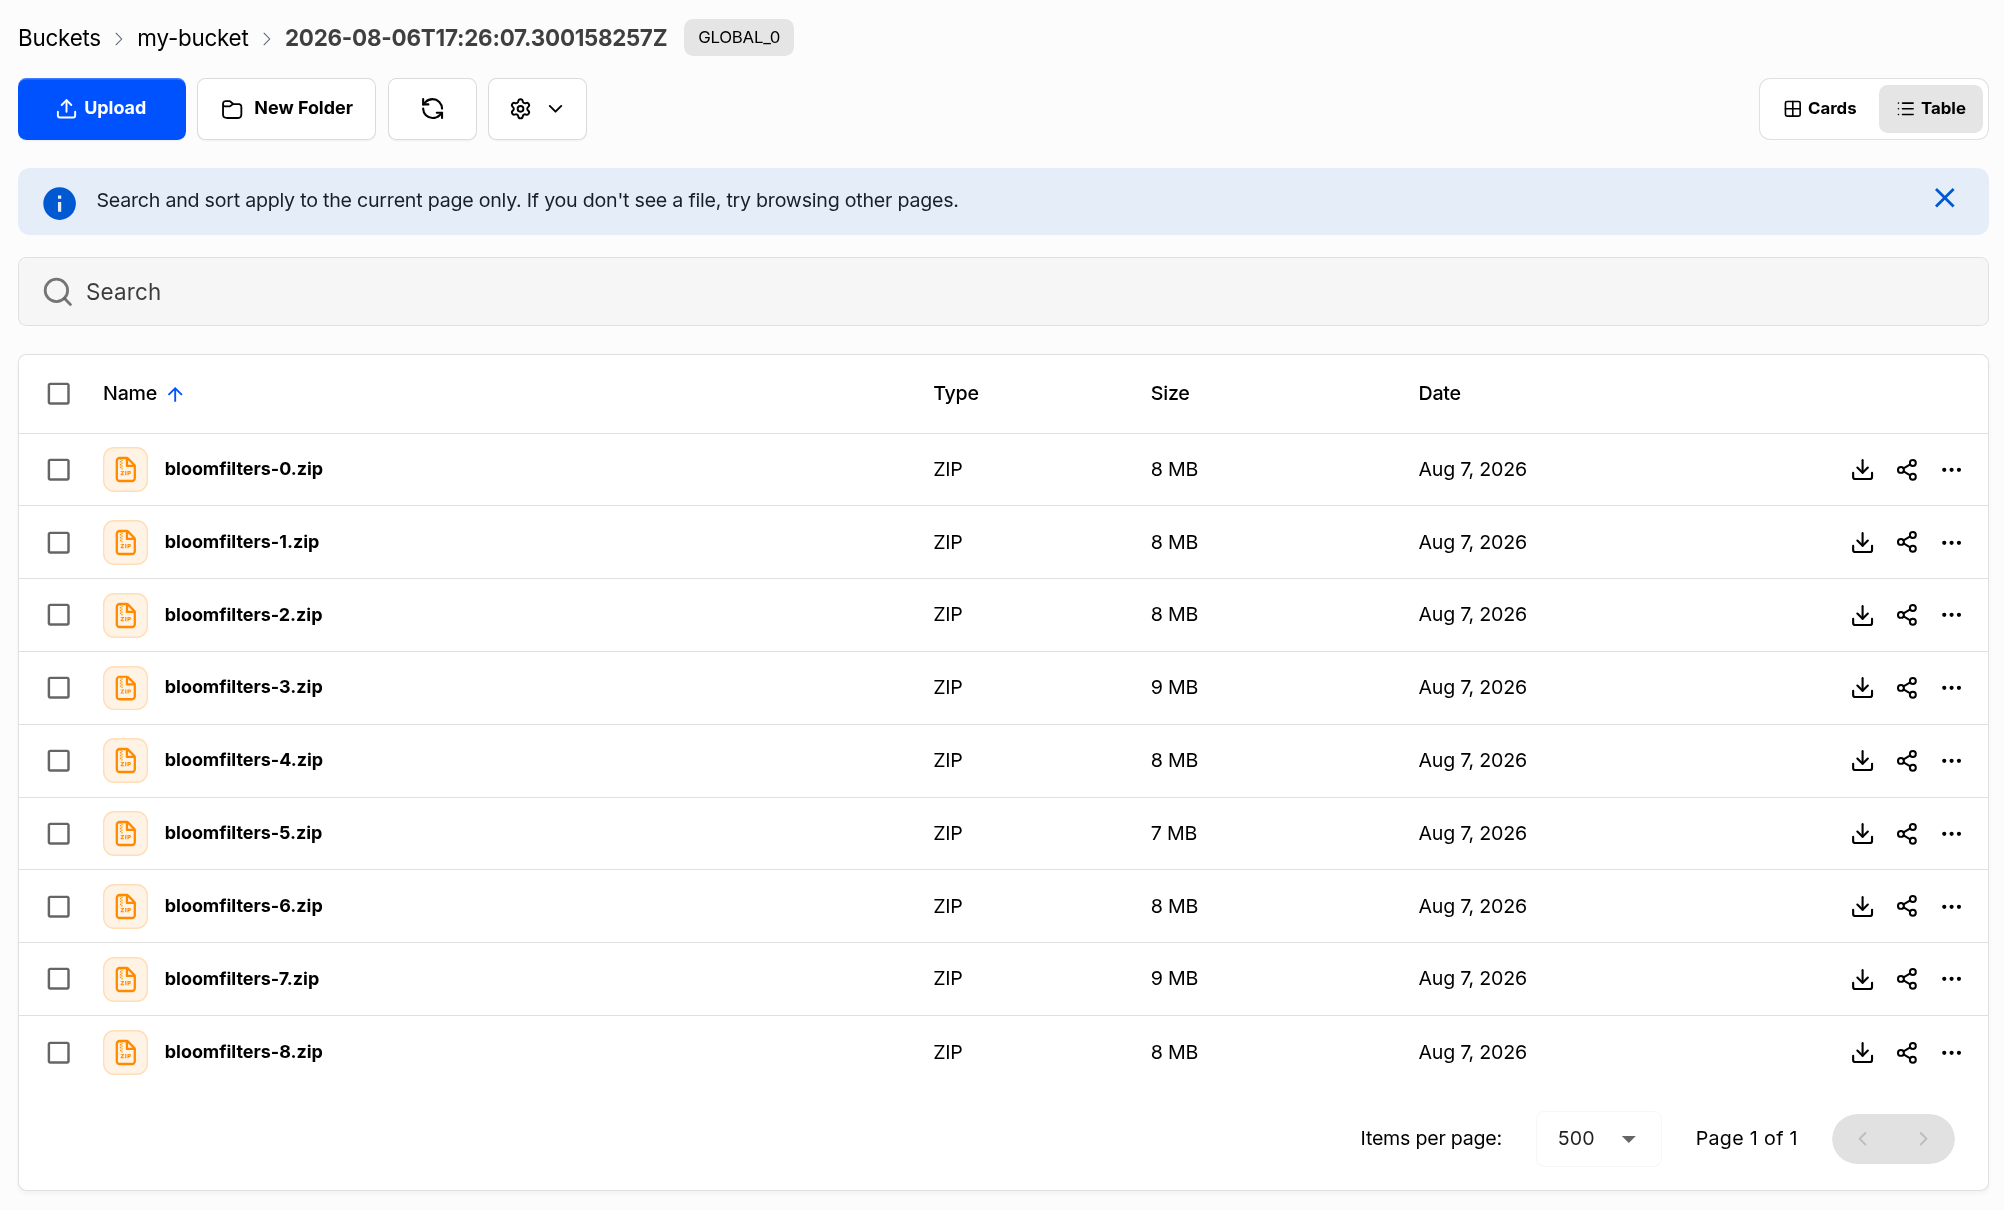
Going to your bucket, you should see something like this:

Content of LATEST file: 2026-08-06T17:26:07.300158257Z

Notice that, this is only bloomfilter generation, this is not push to storagenodes yet, on next post, we’ll study how to push this to our storage nodes. See you then.

gc-sender

This is the service that send bloomfilter to each storagenode.

Strictly speaking, this isn’t belongs to ranged-loop, but what does bloomfilter generation ever do without sending?

EDIT: if you already run core service, you don’t need to run this service separatedly.

Minimum useful command

./satellite-modular gc-sender \
--identity-dir=id/satellite \
--database-options.url="postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt" \
--metainfo.database-url="postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt" \
--garbage-collection.bucket "my-bucket" \
--garbage-collection.access-grant "1MPU..." \
--server.extensions.revocation=false \
--server.use-peer-ca-whitelist=false

Note that this service will run non-stop in a loop, it is safe to stop it at anytime (process will resume when another gc-sender start). NO two gc-sender should be running concurrently, the current code don’t support that, bloomfilter might get send multiple times.

In production environment, some error you might encourter:

2026-08-17T04:07:33Z	INFO	debug:wrapper.debug	debug server is started listening	{"addr": "127.0.0.1:36525"}
2026-08-17T04:07:33Z	INFO	tracing:tracing	Anonymized tracing enabled
2026-08-17T04:07:38Z	WARN	sender:service	Error sending retain filter	{"node_id": "<node_id>", "error": "gc: rpc: tcp connector failed: rpc: dial tcp <ip_address>:28967: connect: connection refused", "errorVerbose": "gc: rpc: tcp connector failed: rpc: dial tcp <ip_address>:28967: connect: connection refused\n\tstorj.io/common/rpc.HybridConnector.DialContext.func1:190"}
2026-08-17T04:08:39Z	WARN	sender:service	Error sending retain filter	{"node_id": "<node_id>", "error": "gc: rpc: tcp connector failed: rpc: dial tcp <ip_address>:28968: i/o timeout", "errorVerbose": "gc: rpc: tcp connector failed: rpc: dial tcp <ip_address>:28968: i/o timeout\n\tstorj.io/common/rpc.HybridConnector.DialContext.func1:190"}
2026-08-17T04:08:40Z	WARN	sender:service	Error sending retain filter	{"node_id": "<node_id>", "error": "gc: retain called with untrusted ID", "errorVerbose": "gc: retain called with untrusted ID\n\tstorj.io/storj/satellite/gc/sender.(*Service).sendRetainRequest:194\n\tstorj.io/storj/satellite/gc/sender.(*Service).RunOnce.func3.1.1:140\n\tstorj.io/common/sync2.(*Limiter).Go.func1:49"}
2026-08-17T04:09:39Z	WARN	sender:service	Error sending retain filter	{"node_id": "<node_id>", "error": "gc: rpc: tcp connector failed: rpc: dial tcp <ip_address>:30033: i/o timeout", "errorVerbose": "gc: rpc: tcp connector failed: rpc: dial tcp <ip_address>:30033: i/o timeout\n\tstorj.io/common/rpc.HybridConnector.DialContext.func1:190"}
2026-08-17T04:09:39Z	WARN	sender:service	Error sending retain filter	{"node_id": "<node_id>", "error": "gc: retain called with untrusted ID", "errorVerbose": "gc: retain called with untrusted ID\n\tstorj.io/storj/satellite/gc/sender.(*Service).sendRetainRequest:194\n\tstorj.io/storj/satellite/gc/sender.(*Service).RunOnce.func3.1.1:140\n\tstorj.io/common/sync2.(*Limiter).Go.func1:49"}
2026-08-17T04:09:42Z	WARN	sender:service	Error sending retain filter	{"node_id": "<node_id>", "error": "gc: retain called with untrusted ID", "errorVerbose": "gc: retain called with untrusted ID\n\tstorj.io/storj/satellite/gc/sender.(*Service).sendRetainRequest:194\n\tstorj.io/storj/satellite/gc/sender.(*Service).RunOnce.func3.1.1:140\n\tstorj.io/common/sync2.(*Limiter).Go.func1:49"}

I think those error are safe, it mostly error from node side.

When gc-sender finish, the directory name will change to sent-2026-08-17T04:02:34.586949988Z (it now have prefix sent).

$audit.Observer

What is $audit.Observer and what is the relationship with [Tutorial] Run your own satellite (part 11) - Satellite auditor and vetting process?

In simplest terms, $audit.Observer is the producer and satellite-modular auditor is the consumer. Records will be store in verification_audits table.

Minimal command to run

./satellite-modular ranged-loop \
--components='$audit.Observer' \
--identity-dir=id/satellite \
--metainfo.database-url "postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt" \
--database-options.url "postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt"

By default, this loop run forever and ranged-loop.interval is 2h, if you want to use your own scheduler, use ranged-loop-once instead.

There are 2 knobs need tuning if the number of segment go up:

ranged-loop.parallelism (default 2), raise this up as segments grow, it splits the stream_id space into N equal UUID ranges (CreateUUIDRanges), one goroutine each.

If you raise ranged-loop-parallelism, it also a good idea to raise database-options.max-open-conns (default 5) to appropriate number.

Notice that, audit traffic (from node) is egress traffic - at least for storj, so don’t overshoot it.

$nodetally.Observer

nodetally.Observer is the at-rest storage accounting for storage nodes — it’s how the satellite figures out how much data each node held, which eventually becomes node payouts.

Result stored in storagenode_storage_tallies table, then another service (rollup) will use this to aggregate into more useful result.

Note that node tally is different from bucket tally, one for storagenode operator, one is for customer.

Minimum command

./satellite-modular ranged-loop-once \
--components='$nodetally.Observer' \
--identity-dir=id/satellite \
--metainfo.database-url="postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt" \
--database-options.url="postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt"

It is safe to run this frequently, the more you run the more samples storage changes at a finer granularity. But make sure no two processes running at the same time or you will pay double the amount of storage.

This may not matter; audit traffic is expected to be low. It’s rare for the entire piece to be downloaded for verification.

$rangedloop.SequenceObserver

rangedloop.SequenceObserver is two different things depending on how you look at it: a generic scheduling wrapper in the rangedloop package, and — in practice, in the satellite — the durability report.

It counts, per segment, how many pieces sit on usable nodes — online, not suspended, not exiting — minus the k needed to rebuild. Then it recounts after deleting the biggest group (subnet, wallet, operator), showing how much of your durability rests on a single point of failure.

- Claude

Though at the moment I’ve not figure out how to structurally format to read the report, this is a cheap attempt to show you what this can do.

Anyhow, should this observer be called durability.Observer instead?

Minimum command

./satellite-modular ranged-loop-once \
--components='$rangedloop.SequenceObserver' \
--durability.classes=last_net \ # last_net,last_ip,wallet,email
--eventkit.destination=otel \
--otel.logging.stdout=pretty \
--otel.logging.print-eventkit=true \
--identity-dir=id/satellite \
--metainfo.database-url="postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt" \
--database-options.url="postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt"

These three flags: --eventkit.destination=otel, --otel.logging.stdout=pretty and --otel.logging.print-eventkit=true are for displaying the result to stdout so you have a vague idea what kind of data you are dealing with.


#TODO: figure out the framework to read/query these data, keywords: class, healthy_pieces, count, missing_providers, placement, exemplars, retrievable_pieces..

$piecelist.PieceList

piecelist.PieceList is a forensic/ops tool, not a production service. It answers one question: this storage node is holding which segment pieces? — and dumps the answer to CSV files.

Minimal command

./satellite-modular ranged-loop-once \
--components='$piecelist.PieceList' \
--piecelist.node-id=12w4HVk... \
--piecelist.target-dir=/tmp/ \
--identity-dir=id/satellite --database-options.url="postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt" \
--metainfo.database-url="postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt"

When it finish, you’ll see some csv files:

/tmp/pieces-12w4HVk...-0.csv
/tmp/pieces-12w4HVk...-1.csv

-0.csv or -1.csv is influence by the number of --ranged-loop.parallelism (default 2), increase this will split into more csv files.

Some content of csv files:

...
17b8df85-8bc9-4c2a-b0b8-44b394787f1f,0,20
17b91812-06cb-43a9-a962-854c77278d6b,0,6
17b93177-4a0c-4f4c-928f-a0a021932094,0,31
17b94b6a-fd2b-4ee6-ae66-336290ebe900,0,36
17b98b85-b6b7-4db4-a7ef-f162cc124e7b,0,4
17b9f3c7-e51f-4d59-a5f3-b18652821d88,0,73
17ba08d4-c300-46af-aa9f-9584c05149ac,0,75
...

Why could it be needed?

$balancer.Balancer, $balancer.Drain, $balancer.Invariant

$balancer.Balancer: Rebalances disk usage across nodes within the same group (grouped by an attribute, eg: last_net, etc…), without necessarily fixing rule violations.

$balancer.Invariant: Fixes placement rule violations — e.g. two pieces of a segment ending up in the same subnet when the placement’s rules forbid that (a “clumping” violation).

$balancer.Drain: Moves pieces off specific nodes that operators want emptied (e.g. nodes being decommissioned).


All this technology is very new (Mar 2026), would be thrill to hear the use case or if storj have use this in production yet?

What is the similar and different between satellite repair and $balancer.Invariant? When to use which?

I think this is mostly about economic, with traditional RS: 29/35/80, satellite operator need to pay atleast: x29 pieces for download, upload is free, so if move fewer than 29, use balancer.Invariant, if move more, use the repair mechanic and only pay for maximum 29 pieces.

Another factor is - repair can only be trigger when heathy pieces drop below certain threshold, this give satellite more flexibility to control when to do it.

What is the different between Graceful Exit and $balancer.Drain?

The most prominent I think is GE is storagenode initiate, but drain/balance is satellite initiate, it use GET_REPAIR / PUT_REPAIR, so traffic is indistinguishable from the normal repair mechanic.

Minimum command:

./satellite-modular ranged-loop-once \
--components='$balancer.Invariant' \
--identity-dir=id/satellite \
--invariant.placement="-1" \ # -1 is all placement ids (placement 0 is the default placement)
--database-options.url="postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt" \
--metainfo.database-url="postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt"
./satellite-modular ranged-loop-once \
--components='$balancer.Balancer' \
--identity-dir=id/satellite \
--database-options.url="postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt" \
--metainfo.database-url="postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt"
./satellite-modular ranged-loop-once \
--components='$balancer.Drain' \
--identity-dir=id/satellite \
# --drain.node-filter \
# --drain.selector \
# --drain.placement="-1" \
--database-options.url="postgres://my_role:123456@127.0.0.1:26257/my_database?sslmode=verify-full&sslrootcert=ca.crt" \
--metainfo.database-url="postgres://my_role:123456@127.0.0.1:26257/my_metainfo_database?sslmode=verify-full&sslrootcert=ca.crt"

Note that, all this should serve as introduction, personally I don’t really know how all this work :slight_smile:.

How to try to run any component

Instead of me painstakingly going through command one by one, I’d show you how to try to run any component.

And from this point onward, I’d only reference about what the component does and NOT how to run it anymore.

Let’s demonstrate using nodeaudit.PieceList and nodeaudit.PieceAudit.

Different between exec and ranged-loop

First, let clear some confusion: in satellite-modular, there are exec and ranged-loop subcommands, internally, they are the same thing, except:

ranged-loop currently have 2 always-on components: piecetracker.Observer and rangedloop.LiveCountObserver and a lot of optional components that already pulled in selector (notice: optional mean it will not run unless you remove optional tag).

exec doesn’t have any component pull in by default.

To turn off 2 default always-on components for ranged-loop, you can use this syntax:

./satellite-modular ranged-loop \
--components='!piecetracker.Observer,!rangedloop.LiveCountObserver,nodeaudit.PieceList'
# now ranged-loop become `exec` subcommand and use nodeaudit.PieceList only

Do you notice sometimes I use ! character prefix? Sometimes $ and maybe no prefix?
! mean exclude, $ is remove optional tag (for components that already pulled in selector), no prefix - directly add a component to selector.

(I often get confused by this system so need to mansplain it for my own understanding).

See how to manipulate components at storj/shared/modular/selector.go at 4baa53fc9c8485c0d51e28f5bea136aeec785c19 · storj/storj · GitHub

nodeaudit.PieceList and nodeaudit.PieceAudit

nodeaudit.PieceList will generate a piece list of a node and put it into a redis stream (though comment in code say they may use jobq in the future).

And nodeaudit.PieceAudit is a service to consume this data.

Some notes for this:

  1. This is an external system, storagenode audit score will not be affect if you run this.
  2. To see the result you need monkit infrastructure (which something we don’t have yet), so this is just an experiment at the moment.

Experiment

I’d do this first:

./satellite-modular ranged-loop \
--components='!piecetracker.Observer,!rangedloop.LiveCountObserver,nodeaudit.PieceList'
Errors:
    argument error: nodeaudit.piece-list.node: required flag missing

Now we need to figure out --nodeaudit.piece-list.node:

./satellite-modular ranged-loop \
--components='!piecetracker.Observer,!rangedloop.LiveCountObserver,nodeaudit.PieceList' -h \
| grep nodeaudit.piece-list.node

    argument error: nodeaudit.piece-list.node: required flag missing
    satellite-modular ranged-loop <--nodeaudit.piece-list.node string> [flags]
        --nodeaudit.piece-list.node string                               Node ID of the node to find pieces for. (required)

Usually, it will be base58 format of node id (use convert-node-id to get it if you query node id directly from database).

After --nodeaudit.piece-list.node is done, the next error should be:

file or directory not found: open /identity.cert: no such file or directory
        storj.io/common/identity.Config.Load:326
        storj.io/storj/shared/modular.IdentityConfig.Load:29
        storj.io/storj/shared/modular.IdentityModule.func1:36
        ...

This is will --identity-dir=id/satellite. Go again:

Error starting master database on satellite api: satellitedb: failed opening database via DBX at "postgres://?application_name=satellite": satellitedb: failed to connect to `user=root database=`: /tmp/.s.PGSQL.5432 (/tmp): dial error: dial unix /tmp/.s.PGSQL.5432: connect: no such file or directory
        storj.io/storj/satellite/satellitedb.open:148
        storj.io/storj/satellite/satellitedb.Open:121
        storj.io/storj/satellite/satellitedb.OpenDBWithMigration:44
        ...

This will be --database-options.url. Again.

Error creating metabase connection on satellite api: metabase: failed to connect to `user=root database=`: /tmp/.s.PGSQL.5432 (/tmp): dial error: dial unix /tmp/.s.PGSQL.5432: connect: no such file or directory
        storj.io/storj/satellite/metabase.Open:136
        storj.io/storj/satellite/metabase.OpenDatabaseWithMigration:37
        ...

This is of course --metainfo.database-url. Again.

Now it work :grinning_face:, verify it with redis-cli -u redis://localhost:6379 XRANGE nodeaudit - +, you should see some data like this:

redis-cli -u redis://localhost:6379 XRANGE nodeaudit - +
...
2567) 1) "1787732420230-0"
      2) 1) "stream_id"
         2) "ffe82cdc90774ac9904fcf2b748d58fb"
         3) "position"
         4) "0"
         5) "pieceno"
         6) "18"
         7) "rootpieceid"
         8) "d79e0a91cac1999f40fdabeb5f0364427b2261539012cc8673a84df913cf6637"
...

Now repeat the same for nodeaudit.PieceAudit.

And after you run nodeaudit.PieceAudit, XRANGE nodeaudit should be come empty set again.

redis-cli -u redis://localhost:6379 XRANGE nodeaudit - +
(empty array)

Hope that with this, in the future you can generate new command for some new components all by yourself.

core service (satellite/run/core.go)

What is core service? It is a collection of components in the core.go file:

// https://github.com/storj/storj/blob/861183073ffd057db41d12b85b3184dacccfcbaa/satellite/run/core.go#L37-L66
func (a *Core) GetSelector(ball *mud.Ball) mud.ComponentSelector {
	return mud.Or(
		Observability(ball),
		mud.Select[*analytics.Service](ball),
		mud.Select[*mailservice.Service](ball),
		mud.Select[*emailreminders.Chore](ball),
		mud.Select[*overlay.Service](ball),
		mud.Select[*offlinenodes.Chore](ball),
		mud.Select[*straynodes.Chore](ball),
		mud.Select[*nodeevents.Chore](ball),
		mud.Select[*audit.ContainmentSyncChore](ball),
		mud.Select[*expireddeletion.Chore](ball),
		mud.Select[*zombiedeletion.Chore](ball),
		mud.Select[*tally.Service](ball),
		mud.Select[*rollup.Service](ball),
		mud.Select[*projectbwcleanup.Chore](ball),
		mud.Select[*rolluparchive.Chore](ball),
		mud.Select[*storjscan.Chore](ball),
		mud.Select[*billing.Chore](ball),
		mud.Select[*repairer.QueueStat](ball),
		mud.Select[*sender.Service](ball),
		mud.Select[*accountfreeze.Chore](ball),
		mud.Select[*accountfreeze.BotFreezeChore](ball),
		mud.Select[*accountfreeze.TrialFreezeChore](ball),
		mud.Select[*accountfreeze.OptOutFreezeChore](ball),
		mud.Select[*dbcleanup.Chore](ball),
		mud.Select[*pendingdelete.Chore](ball),
		mud.Select[*projectlimitevents.Chore](ball),
	)
}

Observability(ball) is an additional of these components:

// https://github.com/storj/storj/blob/861183073ffd057db41d12b85b3184dacccfcbaa/satellite/run/observability.go#L18-L26
func Observability(ball *mud.Ball) mud.ComponentSelector {
	return mud.Or(
		mud.Select[debug.Wrapper](ball),
		mud.Select[*tracing.Tracing](ball),
		mud.Select[*eventkit.Eventkit](ball),
		mud.Select[*profiler.Profiler](ball),
		mud.Select[*DBVersionCheck](ball),
	)
}

Unless you plan to run your satellite exactly as Storj, I don’t think you should run this core service exactly as is.

Two ways to run a modified core service:

  1. use satellite-modular exec and only include components that you need.
  2. use built-in satellite-modular core but remove component that you don’t need, eg:
./satellite-modular core --components='!emailreminders,!accountfreeze.Chore' ...

Each have it pro and cons, but I would recommend using 1. as it give you greater control and easier to manage if you heavily modify your satellite.

nodeaudit.PieceCountHistogram

Builds a distribution of how many pieces of each segment are actually reachable on “participating” nodes (i.e. not disqualified/exited/unknown).

nodeaudit.ColdLegacyStat

Detect pieces sitting on nodes it’s not supposed to - because of placement, i.e. “legacy”/misplaced pieces.

Another function of this is to predict how many pieces will become misplace if a specific placement rule is going to change.

nodeaudit.ExpansionFactor

Computes storage expansion ratios per placement — how much actual storage is used vs. the logical segment size, both for all pieces and for “healthy” pieces only.

What is logical segment size?

PlainSize — size before encryption. (segment.PlainSize, documented as size before encryption).

EncryptedSize — size after encryption, still per segment, what the ranged-loop ExpansionFactor observer calls “logical segment size.” Slightly larger than PlainSize due to encryption overhead/padding - this is the storage customer is billed.

TotalPieceSize — EncryptedSize expanded by erasure coding into N pieces across nodes. This is the real storage node footprint - satellite operator pays storage nodes on this.

How to detect a component is belongs to ranged-loop family?

Use this command on the source code:

grep -rn "Implementation\[\[\]rangedloop\.Observer" --include="*.go" .
./satellite/balancer/mud.go:17:	mud.Implementation[[]rangedloop.Observer, *Balancer](ball)
./satellite/balancer/mud.go:26:	mud.Implementation[[]rangedloop.Observer, *Drain](ball)
./satellite/balancer/mud.go:31:	mud.Implementation[[]rangedloop.Observer, *Invariant](ball)
./satellite/metrics/mud.go:14:	mud.Implementation[[]rangedloop.Observer, *Observer](ball)
./satellite/accounting/nodetally/mud.go:15:	mud.Implementation[[]rangedloop.Observer, *Observer](ball)
./satellite/gc/piecetracker/mud.go:15:	mud.Implementation[[]rangedloop.Observer, *Observer](ball)
./satellite/gc/bloomfilter/mud.go:29:	mud.Implementation[[]rangedloop.Observer, *Observer](ball)
./satellite/nodeaudit/mud.go:21:	mud.Implementation[[]rangedloop.Observer, *PieceList](ball)
./satellite/nodeaudit/mud.go:34:	mud.Implementation[[]rangedloop.Observer, *ExpansionFactor](ball)
./satellite/nodeaudit/mud.go:39:	mud.Implementation[[]rangedloop.Observer, *ColdLegacyStat](ball)
./satellite/nodeaudit/mud.go:44:	mud.Implementation[[]rangedloop.Observer, *PieceCountHistogram](ball)
./satellite/audit/mud.go:58:	mud.Implementation[[]rangedloop.Observer, *Observer](ball)
./satellite/repair/checker/mud.go:49:	mud.Implementation[[]rangedloop.Observer, *Observer](ball)
./satellite/piecelist/mud.go:15:	mud.Implementation[[]rangedloop.Observer, *PieceList](ball)
./satellite/durability/mud.go:44:	mud.Implementation[[]rangedloop.Observer, *rangedloop.SequenceObserver](ball)

What is ranged-loop component family anyway?

It is a collective of components that will scan metainfo database (metabase), if possible, we should group these component together in a single run to save database queries.

Everything is a component

Everything I ever wrote so far about satellite (storj/storj repo), it can be run manually with exec, for example:

satellite-modular api:

func (a *Api) GetSelector(ball *mud.Ball) mud.ComponentSelector {
	return mud.Or(
		Observability(ball),
		mud.Select[*satellite.EndpointRegistration](ball),
		mud.Select[*orders.Chore](ball),
	)
}

Using exec:

satellite-modular exec --components='satellite.EndpointRegistration,orders.Chore' ...

satellite-modular auditor:

func (a *Auditor) GetSelector(ball *mud.Ball) mud.ComponentSelector {
	return mud.Or(
		Observability(ball),
		mud.Select[*audit.Worker](ball),
		mud.Select[*audit.ReverifyWorker](ball))
}

Using exec:

satellite-modular exec --components='audit.Worker,audit.ReverifyWorker' ...

And so on, you can mix and match components however you like it :exploding_head:, see more at satellite/run.

tally and rollup

Storj’s Satellite tracks storage and bandwidth usage through a pipeline of accounting components living in satellite/accounting/:

  • nodetally — already documented here.

  • tally — computes current usage snapshots (how much data exists right now). If this service stop running, when user delete file in bucket, storage usage won’t get reflected.

  • rollup — aggregates raw tallies into daily totals for billing/reporting.

  • rolluparchive — archives old rollup rows so the live table stays small.

Only nodetally belongs to storage node, the other three are on bucket side.

How I run (tally and rollup)/(ranged-loop and core)
A reminder: nodetally belongs to ranged-loop, the other three are just standalone chores.

After some thought, this is how I split these services:

// ranged-loop
satellite-modular exec \
--components='rangedloop.Service,audit.Observer,checker.Observer,nodetally.Observer'
// core
satellite-modular core \
--components='!accountfreeze.BotFreezeChore,!accountfreeze.Chore,!accountfreeze.OptOutFreezeChore,!accountfreeze.TrialFreezeChore,!analytics.Service,!billing.Chore,!emailreminders.Chore,!nodeevents.Chore,!offlinenodes.Chore,!pendingdelete.Chore,!storjscan.Chore' \
--server.use-peer-ca-whitelist=false // core have gc-sender - it need to contact storagenode
...

Explain: original core already contain tally, rollup and rolluparchive, we could save time by just run Core service instead of manually run these three services.

As for ranged-loop, currently I saw that audit.Observer,checker.Observer,nodetally.Observer need to be run permanently, so it make sense to group these into it own service (I call it grouped-ranged-loop service). Edit: must include rangedloop.Service, it the driver for other to run.

Other ranged-loop services, eg: bloomfilter,balancer,etc.. doesn’t make sense for non-stop run, probably will need it’s own scheduler.

This split make sense for my current understanding. Of course, it might change once I gain more insight how the satellite work.

offlinenodes.Chore

File: satellite/overlay/offlinenodes/chore.go

It runs on a timer (Interval, default 1h), scans the overlay/node cache for storage nodes that have gone offline, and emails the node operators about it (chore.mail), with a cooldown (default 24h) and a cap (MaxEmails, default 3) so a dead node doesn’t spam its operator forever. It’s purely an operational/notification job for the storage node network side of Storj.

I consider email is too expensive for this and exclude this from core since , I’ll give node operator a RSS to subscribe to.

billing.Chore

File: satellite/payments/billing/chore.go, wired up in satellite/core.go

This is specifically Storj’s own STORJ-token deposit ingestion pipeline for the hosted Storj cloud billing system.

If you are using your own accounting system, you can also ignore this.